Same preview.
Different target.
The preview points to record_A. A candidate action now targets record_B. Inspect how two saved 27B v1.1 predictions select among the supplied options.
Rank-8 LoRA adapter + FP32 decision head over a pinned Qwen3.8-27B base. Base weights are required separately.
Illustrative UI from synthetic text-state records. No browser actions executed. Playback is edited and does not measure inference latency.
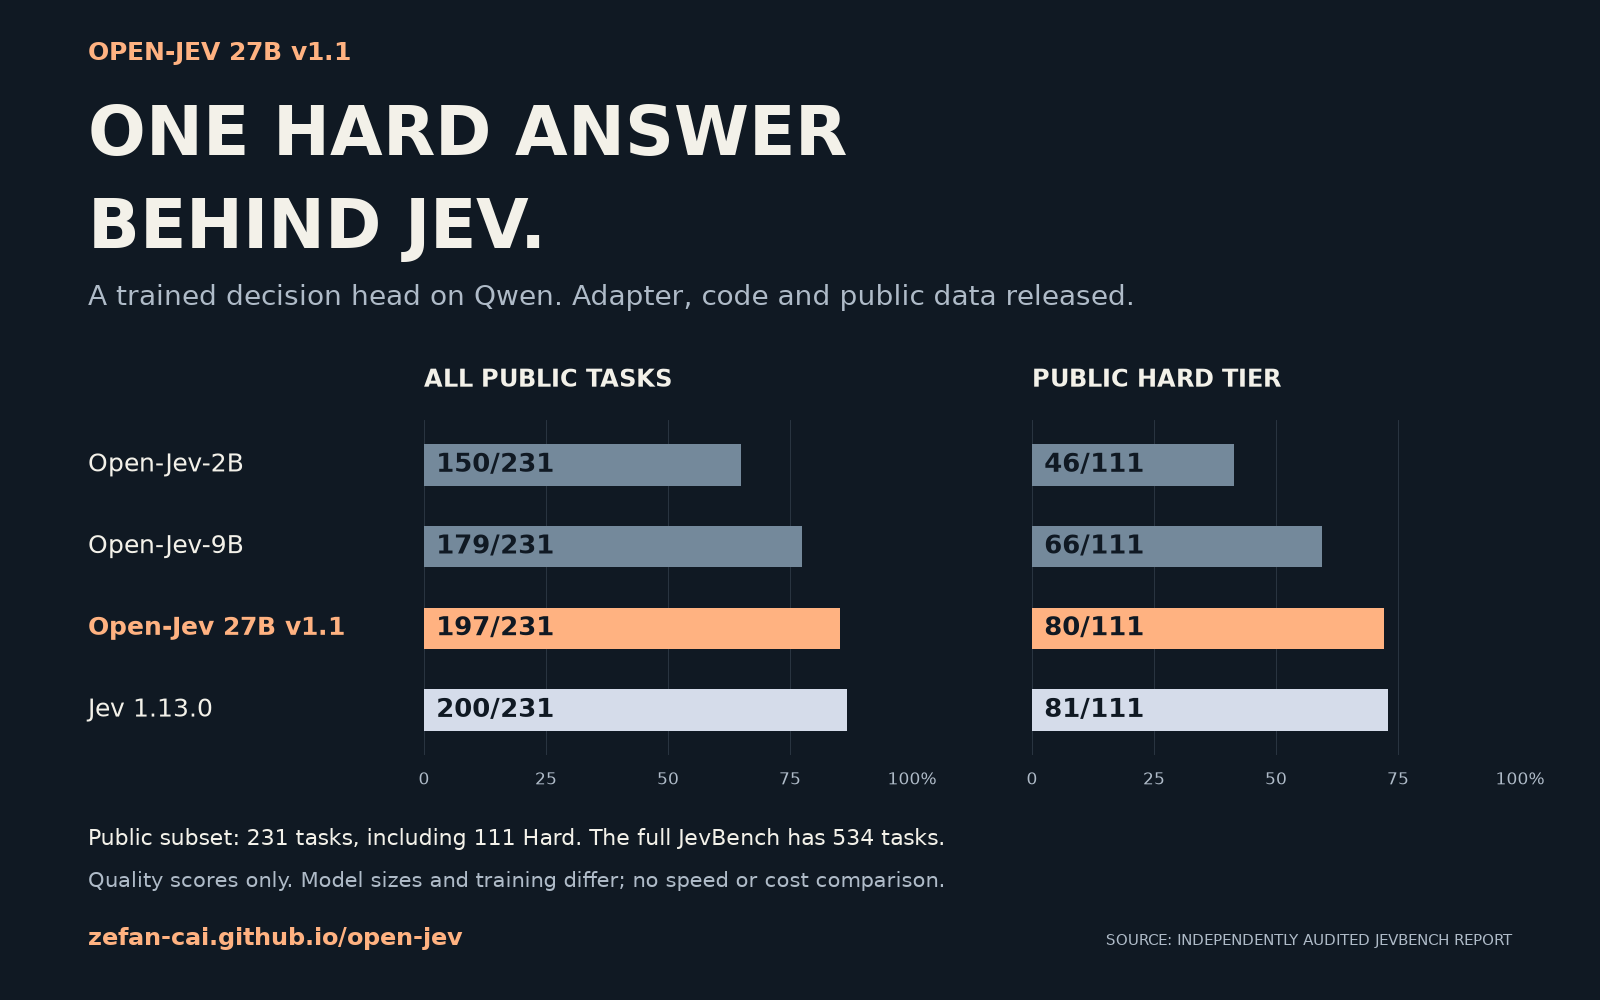
80 out of 111 on Hard.
One answer behind Jev.
Open-Jev-27B-v1.1 scores 197/231 overall (85.28%) and 80/111 Hard (72.07%). Jev scores 200/231 overall and 81/111 Hard.
This is the public 231-task subset of the 534-task benchmark. Model scale, data and prior training differ across Open-Jev versions. Shared multi-GPU evaluation times do not establish single-GPU or HTTP/API latency.
All 43,301 Test and 84,486 OOD rows were evaluated; accuracy uses hard labels. The public dataset is a 326,619-row redistributable projection, excluding 2,053 Wiki records. It is not the complete internal corpus. See all four old/expanded Test/OOD columns · Audit and protocol.
What changes in the input?
Two relevant options
Friendly aliases are display-only. Original candidate IDs remain visible.
The supplied decision policy
- Consequential changes need explicit confirmation.
- The preview target must equal the actual target.
- The session must not be expired.
- The form revision must equal the preview revision.
Among eligible options, choose the fewest interactions; break a tie by lexicographic candidate ID. If none qualifies, choose abstain.
All six options and abstention are shown. Display order is aligned across cases. The original model option order differs and is preserved in the evidence. Probabilities are not accuracy.
Original model input and option order
Recorded logits, probabilities and identity
Source, license and limits
Your move. Then the model's.
Try Snake, tic-tac-toe, Box Runner and Tile Platformer. Choose an action, then inspect the real Open-Jev-27B-v1.1 probabilities across 16 independent recorded game states, including three model/reference disagreements.
Interactive snapshots of saved decisions; no live model inference or new gameplay rollout.
Bring your own categories.
The interactive workbench runs Open-Jev-2B on CPU. Paste messages or import a CSV, define labels, then download the results.
Inspect the decision. Build your own.
Open-Jev-27B-v1.1 is a LoRA adapter and decision head. These selected examples do not establish a general task success rate or a safety guarantee.
27B v1.1 model ↗Code ↗Data ↗Project website ↗