
HeadInfer: Memory-Efficient LLM Inference by Head-wise Offloading
KV Cache Compression & Long-Context Inference
ICML 2025 Workshop on Long-Context Foundation Models · PDF · Code
Move memory by head. HeadInfer keeps the full KV history in CPU RAM and stages individual heads or head groups on the GPU for attention. Chunked prefill limits activation memory; adaptive grouping reduces transfers for shorter contexts; asynchronous prefetch overlaps KV movement with computation. The dense version preserves attention without token eviction or quantization.
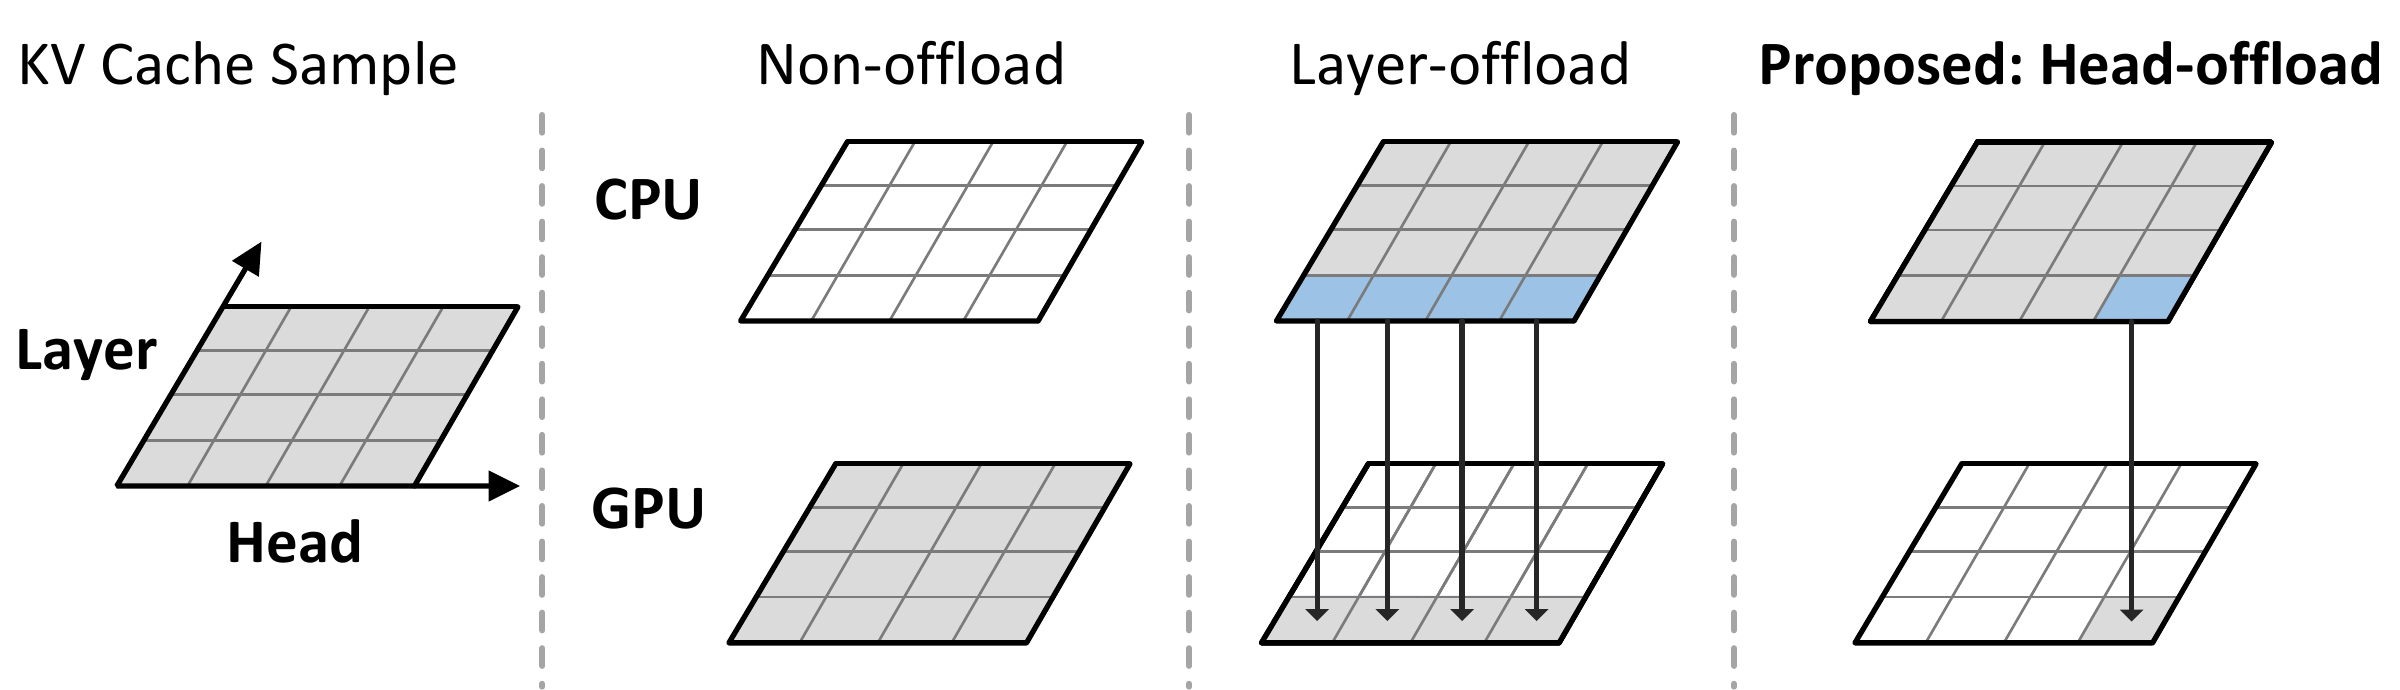
For Llama-3-8B at one million tokens, the paper reports 1 GB of GPU-resident KV cache and 17 GB total GPU memory, compared with estimated BF16 baseline footprints of 128 GB and 207 GB. A single 24 GB RTX 4090 reaches 4,096K context in the tested server with 1 TB host RAM, including a 512 GB KV allocation. LongBench v2 and SCBench evaluate the benefit of avoiding context truncation. The tradeoff is decoding latency: at 20K tokens, throughput is 6 tokens/s versus 33 for standard inference; at one million tokens it falls to 0.15 tokens/s.