
MENTOR: Efficient Autoregressive Image Generation with Balanced Multimodal Control
Multimodal Learning & Generation
Findings of ACL 2026 · PDF · Website · Code
Balance what the reference image preserves with what the text asks to change. MENTOR brings visual and textual inputs into a shared representation, then generates image tokens with an autoregressive decoder. It targets controllable generation under limited training resources.
Training has two stages. Multimodal alignment combines image reconstruction, object segmentation and text-to-image generation to teach both pixel-level fidelity and semantic correspondence. Multimodal instruction tuning then adds complementary tasks that require the generator to use visual details and follow the instruction together.
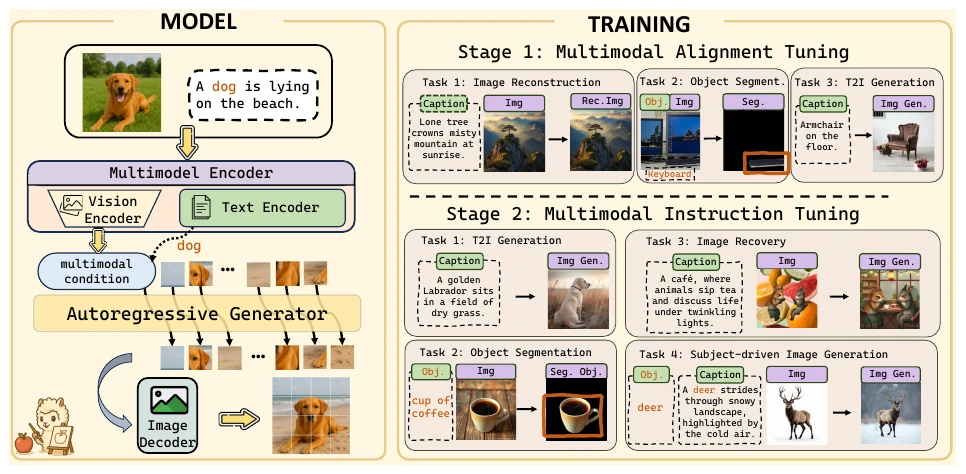
The reported 2.31B-parameter model uses 3 million training examples and reaches a concept-preservation × prompt-following score of 0.47 on DreamBench++ in the paper’s test-time-tuning-free comparison. The experiments also study reconstruction, segmentation and generation from multiple images. The result illustrates a balance between the two input modalities within the evaluated tasks and model setup.
Resources
Checkpoints: Checkpoints