
ML-Bench: Evaluating Large Language Models and Agents for Machine Learning Tasks on Repository-Level Code
ICLR DL4C Workshop 2025 · ICLR Agentic AI for Science Workshop 2025 (Oral) · PDF · Workshop PDF · Website · Code · Data
Measure whether an agent can actually run a machine-learning repository. ML-Bench contains 9,641 annotated examples from 18 GitHub repositories. Each task asks a model to turn a user request into executable Python or Bash code, using the repository’s implementation and documentation to choose the right files, functions and arguments.
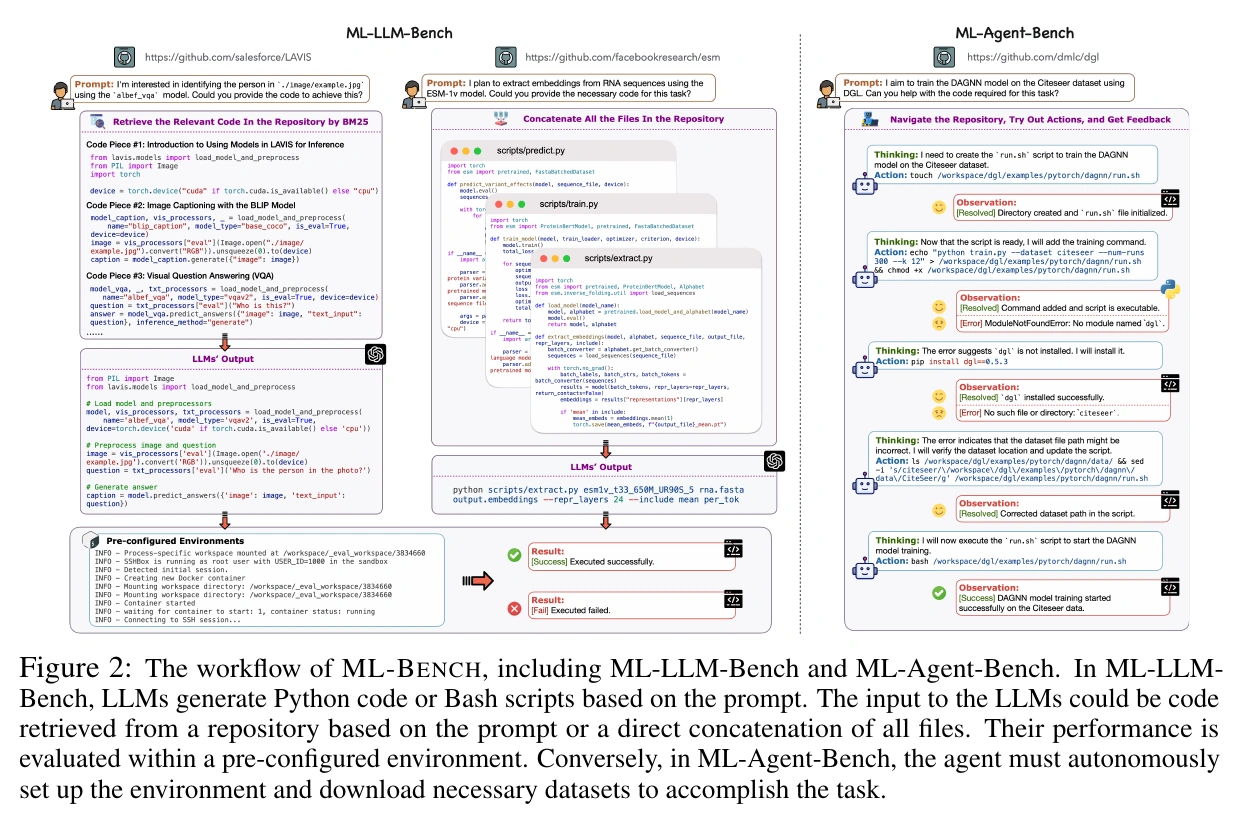
The benchmark separates two workflows. ML-LLM-Bench evaluates generated scripts in a preconfigured environment; ML-Agent-Bench asks an agent to set up its own environment, install dependencies, prepare data and execute the task in a Linux sandbox. This makes repository understanding and feedback from execution part of the evaluation.
In the latest arXiv version’s experiments, GPT-4o exceeds 50% Pass@5 in the Oracle setting of ML-LLM-Bench, while OpenDevin with GPT-4o reports 76.47% success on ML-Agent-Bench. These scores use different setups and metrics. The error analysis identifies incorrect arguments, nonexistent files and Bash generation as remaining obstacles to reliable repository use.