
R-KV: Redundancy-aware KV Cache Compression for Reasoning Models
KV Cache Compression & Long-Context Inference
NeurIPS 2025 · PDF · Page · Code · Video
Keep useful reasoning without keeping every repetition. Long chain-of-thought outputs can repeatedly revisit the same content, yet attention-only cache selection may preserve many similar tokens. R-KV combines attention-based importance with a redundancy penalty computed from cosine similarity between key vectors. It compresses during decoding whenever a buffer of new tokens fills, requiring no retraining.
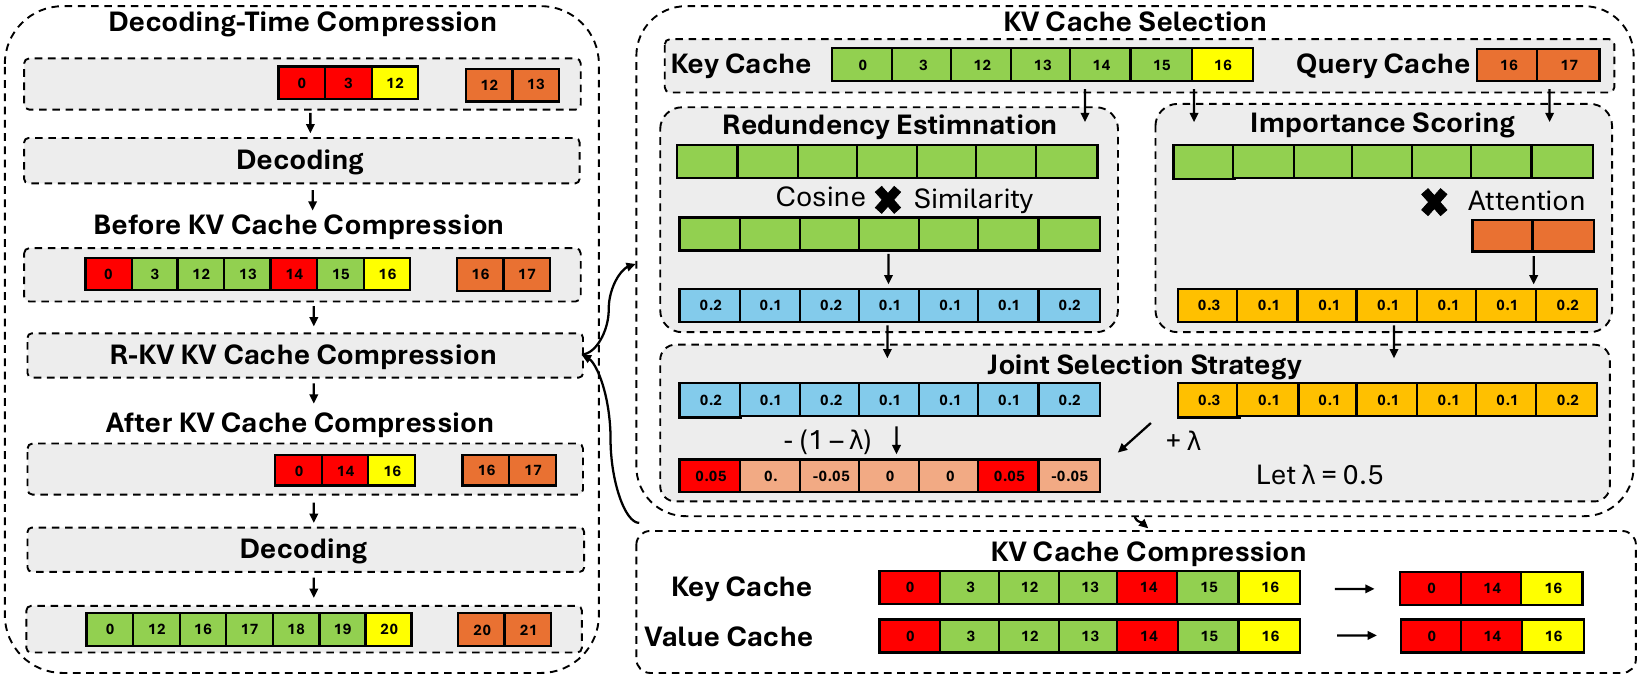
The NeurIPS paper compares R-KV with decoding-adapted SnapKV and full caching on MATH-500 and AIME 2024, using DeepSeek-R1-Distill-Llama-8B and Qwen-14B. With Llama-8B on AIME 2024, a cache budget equal to 10% of average output length preserves full-cache accuracy; at 16%, it reaches 105% of that accuracy. The budget needed to match full caching varies: 34% on MATH-500 for Llama-8B, and 25%/54% on AIME/MATH for Qwen-14B. In a separate Llama3-8B systems benchmark at 16K tokens, a 10% cache budget yields 6.6× throughput, primarily by allowing larger batches. The measurement reports batched-serving throughput.