
Test-Time Training with Next-Token Prediction
Findings of EMNLP 2026 · co-first author · PDF · Code
Use the prompt’s next-token signal to write memory. TTT-NTP reuses selected MLP down-projections as fast weights. Each current MLP activation is paired with the same layer’s contextual state after observing the next token, projected into the write space. This gives the memory a predictive target tied to the model’s own computation. Chunk-parallel training lets later chunks read earlier writes while preserving causality.
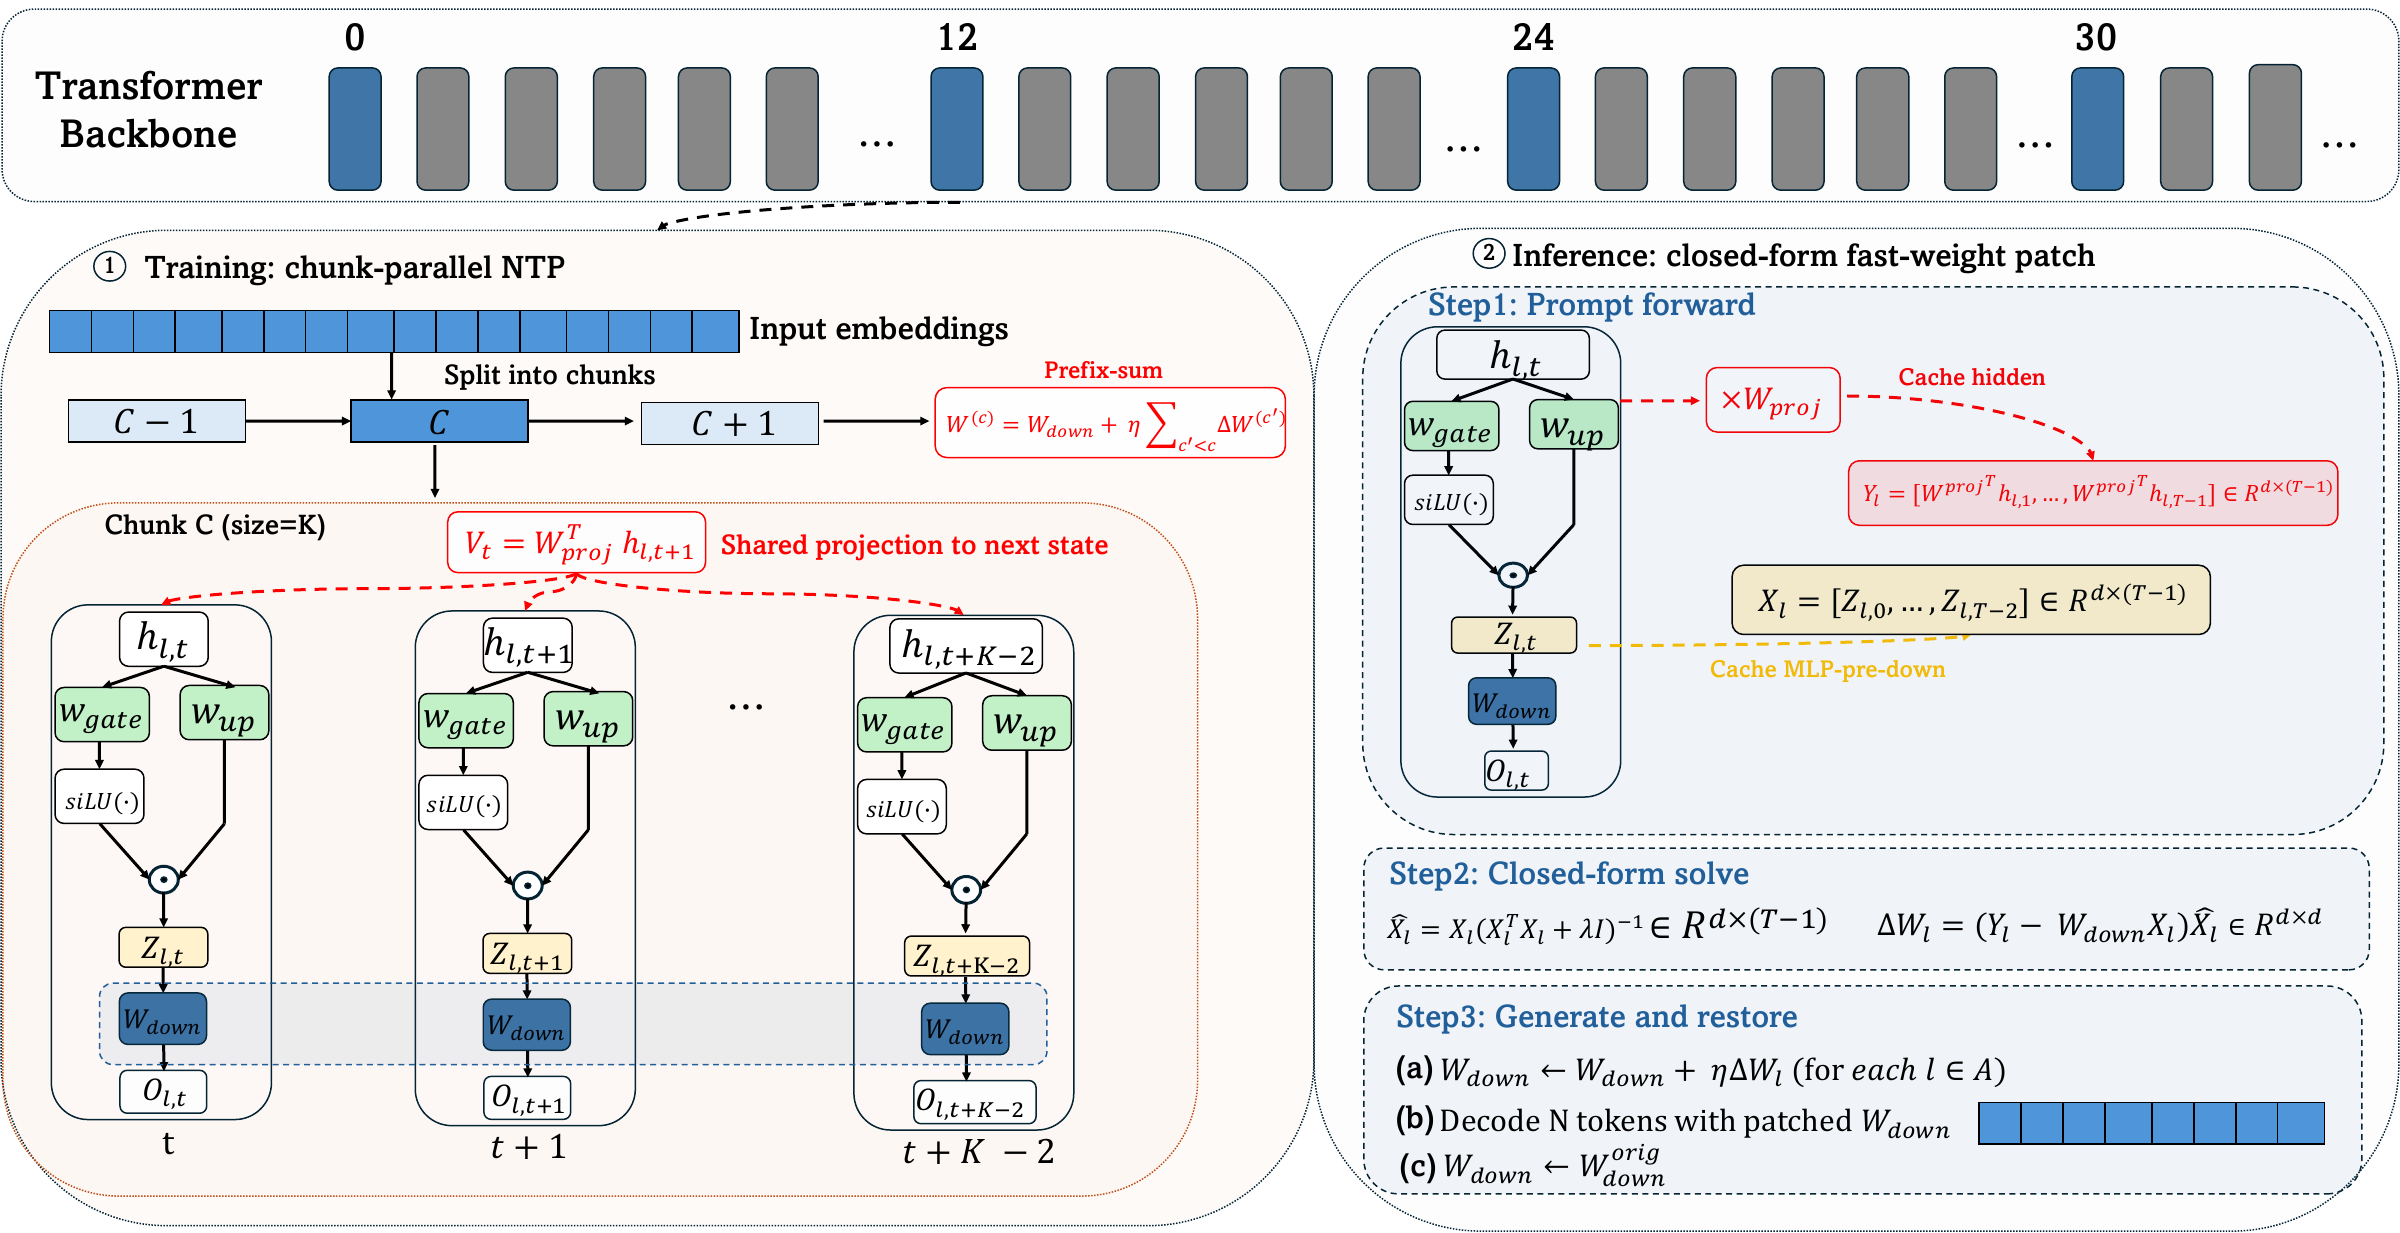
The method first requires continual pretraining. At inference, a prompt forward pass collects activations; a ridge-regression solve patches the down-projections before decoding. The original prompt KV cache is reused, and weights are restored after each sample.
Across Llama-3.1-8B, Mistral-7B-v0.3, Qwen3-4B and Qwen3-0.6B, mean RULER Full-13 accuracy over 4K–32K contexts improves over the released backbones by 3.90, 3.03, 4.06 and 2.88 percentage points. On LongBench-v2’s 215-question medium split, evaluated with a shared 32K-token budget and head-and-tail truncation, accuracy increases from 25.6 to 31.2 on Llama and 26.5 to 30.2 on Mistral. Aggregate commonsense and knowledge scores remain comparable.