
VeCAF: Vision-language Collaborative Active Finetuning with Training Objective Awareness
ACM Multimedia 2024 · PDF · Code
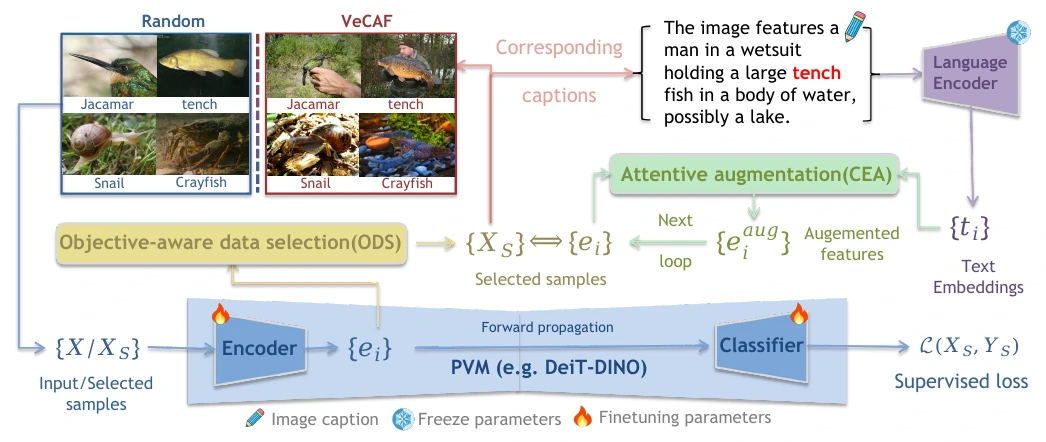
Select training examples for the objective the model needs to reach. VeCAF studies active fine-tuning when images already have labels and captions. It repeatedly chooses a small subset of a larger labeled dataset to adapt a pretrained vision model efficiently.
Objective-aware data selection uses the current model and training objective to find informative examples while maintaining diversity. Cross-attentive embedding augmentation then incorporates the selected images’ caption representations into their visual features. Text edits can also guide selection toward target-domain properties in the paper’s out-of-distribution experiments.
On the reported ImageNet-1K setup, VeCAF needs 3,075 training batches versus 10,250 for full-data fine-tuning to reach the target accuracy, about 3.3× fewer batches. Experiments also cover CIFAR-10, Caltech101 and ImageNet-C. This measures training-batch efficiency under the paper’s selection loop and pretrained-model settings; selecting data also has a computational cost.